
Jump to section
I’ll be honest: the first 200 prompts I ever wrote to ChatGPT were mostly terrible. Vague requests. No context. Confused outputs. I’d stare at the screen wondering why it kept giving me the generic paragraph soup when I’d asked for something specific.
The shift happened when I stopped thinking of prompting as “asking a question” and started thinking of it as briefing a contractor. You wouldn’t hire a copywriter and say “write me something good.” You’d tell them the audience, the goal, the tone, the length, and show them an example you liked. ChatGPT needs exactly the same thing.
Three years and a few thousand client prompts later, here’s what I actually know to be true—with the business results to back it up.
What’s Actually Different About Prompting in 2025
The models have gotten smarter. That sounds obvious, but it matters: you can now do more with a well-structured single prompt than you could with a five-turn conversation in 2023. The downside? The gap between a mediocre prompt and a great one has also widened. Good models punish lazy inputs harder.
| Aspect | 2023 Approach | 2025 Approach |
|---|---|---|
| Strategy | Random trial-and-error | Systematic, repeatable frameworks |
| Context | Single-shot prompts | Multi-turn, layered conversations |
| Complexity | Simple Q&A | Chain-of-thought reasoning |
| Personalization | Generic requests | Role-specific personas + domain context |
| Quality Control | Manual re-reading | Built-in validation steps |
| Integration | One-off tasks | Workflow automation, agentic flows |
The other big shift: agentic AI. By mid-2025, many businesses aren’t just prompting ChatGPT for outputs—they’re building systems where ChatGPT orchestrates multi-step tasks autonomously. Prompt engineering is now architecture work, not just wordsmithing.
The 6 Core Prompting Strategies (Ranked by Impact)
I’ve tested all of these across industries. The ranking is based on what moved the needle most quickly for non-technical users who needed results fast.
Role-Based Prompting
Assign ChatGPT a specific expert identity before the actual task. “You are a senior UX copywriter specializing in SaaS onboarding flows” gives wildly better output than “write copy.”
Chain-of-Thought
Ask the model to reason step-by-step before giving an answer. This dramatically reduces confident-but-wrong outputs—especially for analysis and decisions.
Few-Shot Learning
Give 2–3 examples of what “good” looks like. Style matching, tone consistency, formatting—nothing teaches these better than showing, not telling.
Context Stacking
Layer background information in logical order: industry → company → situation → task. Think of it as loading up the right RAM before asking for the computation.
Constraint Definition
Define what you don’t want as clearly as what you do. “No bullet points. No preamble. Under 150 words. No use of the phrase ‘in today’s world.'”
Meta-Prompting
Ask ChatGPT to critique and improve its own outputs. “What did you miss? What assumptions did you make? Rewrite with those corrections.” This one feels almost like cheating.
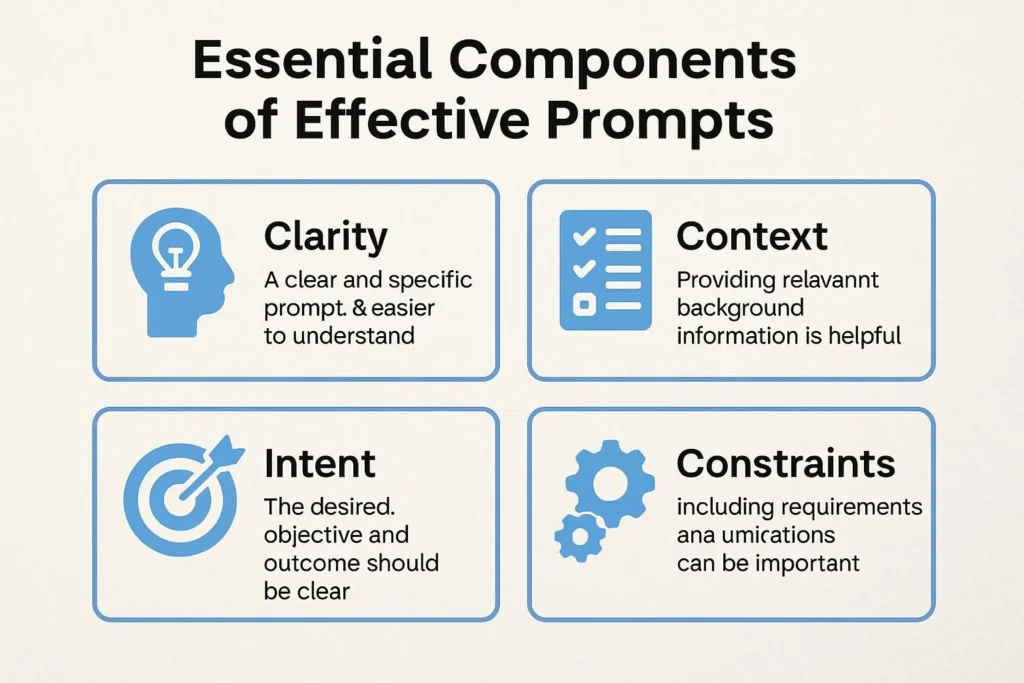
Anatomy of a Great Prompt
Most bad prompts fail for the same reason: they jump straight to the request without any setup. Here’s the structure I use for anything more complex than a quick question.
The Four Layers
The “Sandwich Method” Revisited
You’ve probably seen “context → task → context” recommended before. It works. But the real trick is what goes in that second layer of context: your quality criteria. Not just what to write, but how to measure whether it’s good.
This forces the model to reason from the reader’s perspective, not just execute the literal request.
Advanced Techniques Worth Your Time
Chain-of-Thought 2.0: Parallel Reasoning Paths
Classic chain-of-thought says “think step by step.” The 2025 upgrade adds parallel tracks—you ask the model to consider multiple reasoning paths before committing to one.
The magic is in that last instruction. Forcing ChatGPT to surface conflicts means you get the nuance, not just the most agreeable-sounding answer.
The Self-Critique Loop
One of the most underused techniques, full stop. After ChatGPT gives you an output:
Real result from a client project: A legal tech startup used this loop on contract risk summaries and went from 71% accuracy (first-pass outputs) to 94% accuracy (after two self-critique rounds). The model caught its own overconfidence on ambiguous clauses.
Agentic Prompting Basics
If you’re starting to build workflows rather than just write individual prompts, the structure shifts. You’re now giving ChatGPT a goal and letting it plan the steps, not just execute one.
Real-World Results: Three Case Studies
10,000 Product Descriptions in Weeks, Not Months
They built a reusable prompt template combining: a copywriting specialist persona, four brand voice constraints, a product specification input format, and three example descriptions at different price points. One template, adapted per category.
Contract Risk Review: From 70% to 94% Accuracy
The key insight: they stopped treating ChatGPT as a one-shot answer machine and built a two-stage process. First pass for identification. Second pass (self-critique loop) for challenge and refinement. Human review only on flagged ambiguities.
Multilingual Support with Cultural Adaptation
They found the critical detail: generic “translate and respond” prompts produced technically correct but tonally wrong replies in some markets. Adding cultural communication style notes (“direct is preferred in German contexts; more formal acknowledgment expected in Japanese contexts”) fixed it.
The Mistakes I See Most Often
These are the ones that cost real time and produce the most frustration. I’ve made all of them.
| Mistake | What Actually Happens | The Fix |
|---|---|---|
| Over-engineering the prompt | The model gets confused by contradictory instructions and hedges everything | One objective per prompt. Break complex goals into sequential prompts. |
| No output format specified | You get prose when you wanted a table. Or bullets when you needed paragraphs. | Always end with: “Format as: [X]. Length: approximately [Y].” |
| Context overflow | Too much background dilutes the signal. The model doesn’t know what matters. | Prioritize context by relevance. Most tasks need 3–4 sentences, not 3 paragraphs. |
| Accepting the first response | First outputs are drafts. Always. | Build in one self-critique round as standard practice. |
| Ignoring bias risk | Outputs reflect training data patterns that may not serve your audience | Explicitly prompt: “Check this response for assumptions that might not apply to [specific audience].” |
Ethics You Can’t Skip
I won’t pad this section with platitudes. Here are the three things that actually matter in practice:
Disclose when you use AI for anything customer-facing. Not buried in a footer — meaningfully disclosed. Trust takes years to build and minutes to destroy.
Fact-check the specifics. ChatGPT sounds confident when it’s wrong. Statistics, citations, legal details, medical claims — verify everything before it leaves your desk. I add a standard “flag anything you’re uncertain about” instruction to analytical prompts as a minimum hygiene step.
Audit your prompts for embedded bias. If you’re using ChatGPT for hiring support, customer scoring, or anything consequential, add an explicit bias-check step. “Review this output and identify any patterns that could disadvantage specific demographic groups.” It doesn’t catch everything, but it catches some.
Your 12-Week Implementation Plan
Foundation: Audit and Baseline
Document your top 5 current AI use cases. Run each with your current prompts and score outputs 1–10. These are your baselines. You’ll need them to prove improvement later.
Strategy: Build Your Template Library
Convert your top 5 use cases to structured four-layer prompts (role / context / constraints / task+format). Test each against your baselines.
Advanced: Chain-of-Thought and Self-Critique
Add chain-of-thought reasoning to your analysis prompts. Introduce self-critique loops on high-stakes outputs. Build your few-shot example library for recurring content types.
Optimization: Scale and Document
Review performance data. Retire what didn’t work. Standardize what did. Document your best prompts so the team can use them. This is how prompt engineering becomes organizational capability, not just personal skill.
Quick-Start Checklist
- Add a role to your next prompt before anything else. Do this today.
- Specify output format explicitly — length, structure, what to exclude.
- Run one self-critique loop on your next important output.
- Save three prompts that worked well this week as reusable templates.
- Add a bias-check step to any prompt used for consequential decisions.
- Measure something. Before/after time. Revision cycles. Output score. Pick one metric.
Frequently Asked Questions
How long should an effective ChatGPT prompt actually be?
Can I use the same prompt across ChatGPT, Claude, and Gemini?
What’s the ROI of proper prompt engineering training?
How do I know if my prompts are getting better?
Should I hire a dedicated prompt engineer in 2025?
What’s the difference between prompt engineering and prompt hacking?
Related Resources on AI Earner Hub
If this guide helped, these companion pieces go deeper on specific areas:
- → The Complete ChatGPT Business Integration Guide
- → Agentic AI Workflows: A Practical Introduction
- → Prompt Template Library for Small Business Owners
- → AI Ethics Checklist for Business Use
Get the Prompt Engineering Toolkit
Templates, role personas, a bias checklist, and a prompt scoring rubric—everything in this guide, packaged for immediate use.
Download Free Toolkit →Sources & References
- → Gartner AI Survey 2025 — Enterprise AI adoption statistics
- → OpenAI Research Blog — Chain-of-thought and prompting effectiveness
- → Wei et al. (2022) — “Chain-of-Thought Prompting Elicits Reasoning in LLMs”
- → Learn Prompting — Open-source prompting techniques reference
- → Anthropic Research — Constitutional AI and instruction-following
Last updated: April 30, 2025 · Reading time: ~14 minutes · Content reviewed for accuracy against GPT-4o and o3 model behavior · aiearnerhub.com
OpenAI Prompt Engineering Guide 2026 – Master AI Prompts
The Ultimate Free AI Guide for Beginners (2026): Master AI Step-by-Step—No Coding Required
Prompt Engineering Best Practices: 2026 Guide
Top 10 Prompt Engineering Strategies for 2026: Unlock AI Potential and Boost Productivity by 40%
AI Use Cases in Daily Life: The Only Framework That Actually Works