

OpenAI Prompt Engineering:
The Complete 2025 Masterclass
Everything you actually need — from first principles to the exact GPT-5.2 techniques Cursor, Fortune 500 teams, and OpenAI’s own engineers use daily. No fluff, no recycled advice.
TL;DR — Read this first
- Prompt engineering is the single highest-ROI skill you can add to your AI workflow right now — studies show 40–60% task performance gains.
- GPT-5 and GPT-5.2 respond best to outcome-oriented prompts, not step-by-step instructions — that’s the biggest shift vs. GPT-4.
- Chain-of-thought, role assignment, and negative prompting are still the three core techniques that move the needle.
- Salary data is real: median prompt engineer pay hit $126K in late 2025, senior packages cross $270K+.
- The job title may fade, but the skill never does — it’s becoming table stakes for every knowledge worker.
Table of Contents
What is Prompt Engineering?
Prompt engineering is the practice of designing and optimizing inputs to AI language models to get precise, useful, reproducible outputs. Think of it less like “asking a chatbot a question” and more like writing a detailed brief for the world’s most capable — but very literal — specialist.
Here’s the uncomfortable truth nobody tells beginners: the model isn’t the bottleneck. You are. The same GPT-5 that produces garbage for an unprepared user will write a pitch deck that closes deals for someone who’s spent two weeks learning this craft. Same model, wildly different results.
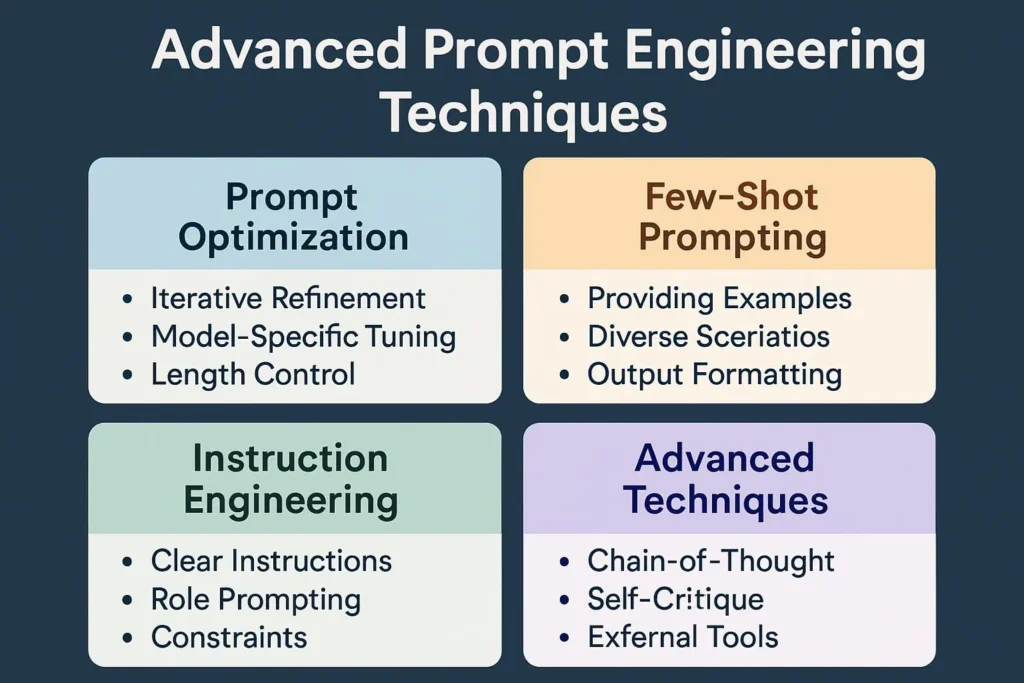
“A reasoning model is like a senior co-worker. You can give them a goal to achieve and trust them to work out the details. A GPT model is like a junior coworker — they’ll perform best with explicit instructions.” — OpenAI Prompt Engineering Guide
At its core, effective prompting combines three disciplines: linguistics (how you phrase things matters enormously), psychology (framing shapes what the model prioritizes), and systems thinking (understanding how information flows through a model’s context window). You don’t need a computer science degree. But you do need to think carefully.
Why It Matters More in 2025 — Not Less
There’s a contrarian narrative floating around that prompt engineering is becoming obsolete because models are getting smarter. Partly true, mostly wrong.
Yes, GPT-5 and its successors require less hand-holding than GPT-3.5. The days of needing to carefully specify “respond in English” are gone. But what’s happened is that the ceiling has risen — dramatically. You can now accomplish things with a well-crafted prompt that would have required custom software 18 months ago. The skill doesn’t become less useful; it becomes more leveraged.
OpenAI’s own documentation for GPT-5.2 explicitly notes that it benefits from “explicit scope and verbosity constraints” and performs better when you define what good looks like rather than describing every step. The model got smarter. The craft of prompting evolved with it — it didn’t disappear.
The real story: “Prompt Engineer” as a standalone job title is fading, yes. What’s replacing it is every knowledge worker being expected to prompt well. Nationwide Insurance rolled out company-wide AI training with prompt engineering as one of its most popular modules. Their CTO put it plainly: “We see this becoming a capability within a job title, not a job title to itself.” That’s the shift. And it means the stakes for learning this properly are higher, not lower.
Core Principles of Effective Prompt Engineering
1. Specificity over cleverness
Every experienced prompt engineer has the same scar from the same mistake: writing a clever, elaborate prompt when a specific, boring one would have worked better. The model doesn’t reward wordplay. It rewards clarity.
Compare these two:
Help me with marketing for my business.
Create a 7-day Instagram + TikTok content calendar for a sustainable fashion brand. Target audience: urban millennials, 25–34. Tone: honest and slightly irreverent. Include one educational post, two product-feature posts, one behind-the-scenes post, and three engagement/question posts per platform.
Specificity includes: format, length, tone, target audience, constraints, and what success looks like.
2. Context is the secret weapon
Models don’t know your situation unless you tell them. The more relevant context you include — your industry, your audience’s sophistication level, the actual goal behind the task — the more targeted the output. Think of it as the difference between asking a consultant “can you help with our pricing?” versus handing them your P&L, competitor data, and customer interview notes first.
3. Role assignment still works
Assigning a role (“Act as a senior financial analyst with expertise in SaaS metrics…”) activates related patterns in the model’s training. It shapes vocabulary, depth of analysis, and the types of caveats it includes. This isn’t magic — it’s signal compression. You’re efficiently communicating a whole set of expectations in one sentence.
4. Define the outcome, not the process (GPT-5+ specific)
This is the biggest change with newer models. OpenAI’s official guidance for GPT-5.2 states it explicitly: “Avoid carrying over every instruction from an older prompt stack. Legacy prompts often over-specify the process because earlier models needed more help staying on track.” With GPT-5.2, describe what a good result looks like, what constraints matter, and what the answer should contain. Let the model choose the path.
Use GPT-5’s meta-prompting capability: ask the model to improve its own prompt before running the actual task. Works surprisingly well and costs almost nothing extra in tokens.
5. Negative prompting — underused, highly effective
Telling the model what not to do is just as powerful as telling it what to do. “Don’t include obvious advice.” “Avoid bullet-point lists — write in flowing prose.” “Don’t mention competitors by name.” These constraints eliminate the generic slop that AI defaults to when it’s coasting.
Advanced Prompt Engineering Techniques
Chain-of-Thought (CoT)
Direct the model to show its reasoning before reaching a conclusion. Massively improves accuracy on complex tasks — up to 85% gain on reasoning benchmarks. Phrase it: “Work through this step by step, showing your logic at each stage.”
Few-Shot Prompting
Include 1–3 examples of the input-output pattern you want. The model pattern-matches against them. Most useful when you need highly specific formatting or domain-specific tone that’s hard to describe in words.
Temperature Control
Low temp (0.1–0.3): factual, analytical tasks where consistency matters. High temp (0.7–1.0): brainstorming, creative writing, ideation. Most people never change this setting and leave productivity on the table.
Self-Consistency
Run the same complex prompt 3–5 times, then compare outputs. The correct answer tends to appear in the majority. Overkill for routine tasks, but invaluable for high-stakes decisions.
Prompt Scaffolding
Wrap user inputs in structured templates with hard constraints — “respond only in JSON”, “always include a risk assessment”, “output nothing outside these tags.” Dramatically increases reliability in production systems.
Meta-Prompting
Use the model to optimize its own prompts. Feed it your draft prompt, ask it to identify weaknesses and rewrite it. GPT-5 is genuinely good at this — OpenAI explicitly recommends it for iterative optimization.
Multi-turn conversation design
For complex projects, design the conversation as a series of exchanges rather than one massive prompt. Start with context-setting, then narrow progressively. This is especially powerful with o1 (128K context) and GPT-5 (1M+ context) — you can carry a rich project brief across an entire working session.
With GPT-5.2 specifically, over-specifying the process can reduce output quality. The model infers better paths than your step-by-step instructions. Trust it more than you trust GPT-4o.
Model Comparison & Selection Guide (May 2025)
OpenAI’s model lineup has expanded considerably. Here’s the honest breakdown of what to use when — based on actual capability profiles, not marketing copy.
| Model | Context Window | Input Cost / 1M tokens | Output Cost / 1M tokens | Multimodal |
|---|---|---|---|---|
| GPT-5.2 | 1M+ | ~$15 | ~$60 | Full (text, image, video) |
| GPT-5 / o1-preview | 128K | $15 | $60 | Images + text |
| GPT-4o | 128K | $2.50 | $10 | Image + text |
| GPT-3.5 Turbo | 16K | $0.50 | $1.50 | Text only |
Pricing as of May 2025. Always verify current rates at openai.com/api/pricing — they change frequently.
Ready-to-Use Prompt Templates
These are not theoretical — they’re the templates I’ve seen produce consistent, high-quality results across dozens of use cases. Copy, adapt, iterate.
Blog post / long-form content
Role: Expert content writer specializing in [INDUSTRY].Task: Write a comprehensive guide about [TOPIC] for [TARGET AUDIENCE].Requirements:- Length: [WORD COUNT]- Tone: [professional / conversational / authoritative]- SEO keywords: [PRIMARY + 2-3 SECONDARY KEYWORDS]- Include: practical examples, a comparison section, and a clear CTA- Do NOT: use filler phrases like "in today's world" or "it's important to note"Format: H2 headings every ~300 words. Short paragraphs (3-4 lines max). No bullet overload.
Strategic business analysis
Role: Senior business analyst with 15+ years in [INDUSTRY].Task: Analyze [SITUATION/PROBLEM].Framework:1. Current state (what's actually happening, not what should be)2. Root causes (go 3 levels deep — don't stop at symptoms)3. Risk-ranked opportunities4. Specific, sequenced recommendations with owners and metrics5. What could go wrong with recommendation #1Constraints: Data-driven where possible. Flag assumptions explicitly. No consultant-speak.
Code generation (GPT-5 optimized)
Stack: [FRAMEWORK + LANGUAGE]Codebase style: [modular / monolithic / describe existing conventions]Task: Build [FEATURE] that does [OUTCOME].Requirements:- Blend into existing code conventions — don't introduce new patterns- Include error handling and edge cases- Add validation commands: unit tests for changed behavior, type checks, build checksDo NOT: Use deprecated APIs. Introduce new dependencies without flagging them.
Multimodal image analysis (GPT-5.2 / o1)
Role: [e.g., data scientist / UX researcher / medical imaging specialist]Task: Analyze the attached image step by step.Focus specifically on: [ELEMENTS — e.g., layout hierarchy, data patterns, anomalies]Output format: [structured JSON / narrative report / bullet summary]Do NOT: Speculate beyond what's visible. Flag uncertainty explicitly.
Industry-Specific Applications
Content marketing & SEO
The biggest win here isn’t writing articles faster — it’s the research and brief-creation phase. A well-prompted model can analyze search intent, extract competitor angles, build keyword clusters, and draft an editorial brief in minutes. From there, the actual writing is just execution.
One digital marketing team reported a 400% increase in content output after systemizing their prompts. The important caveat: quality maintenance required a human review step. You still need editorial judgment. The model handles the mechanical; you handle the strategic.
Software development
GPT-5’s official prompting guide (based on real collaboration with Cursor’s engineering team) reveals a counterintuitive finding: for large codebases, the highest-leverage prompts aren’t the ones that write the most code. They’re the ones that establish coding conventions, directory structure, and design principles so that every subsequent generation “blends in” naturally.
Cursor engineers found that prefacing code prompts with a <code_editing_rules> block describing existing conventions (framework, component structure, state management approach) dramatically improved output quality — more than any other single prompt change.
Healthcare & compliance
In high-stakes domains, prompt scaffolding becomes essential. The goal isn’t clever prompts — it’s constrained ones. Explicitly telling the model what it cannot say, what it must cite, and when to escalate to a human creates reliable guardrails. Include diversity constraints (“Consider varied demographics including age, gender, ethnicity”) to counter well-documented bias patterns in medical AI.
Finance & legal analysis
Financial analysts are seeing the most transformative gains in document synthesis — processing earnings calls, 10-Ks, and analyst reports simultaneously and extracting structured insights. The key prompt pattern: define exactly what “analysis complete” looks like before the model starts. Vague requests produce vague financial analysis.
The 5 Mistakes That Kill Your Results
- Vague instructions with no format specification
“Help me write an email” could mean 20 different things. The model picks one. Yours.
→ FIX: Specify recipient, purpose, desired length, tone, and one specific action you want them to take. - Using GPT-4-style over-specification with GPT-5 models
Copying old prompts into newer models produces stiff, mechanical output. The model tries to literally follow each micro-instruction instead of understanding the goal.
→ FIX: Shift from “do step 1, then step 2, then step 3” to “the output should look like X, feel like Y, achieve Z.” - Treating the first output as final
No professional writer submits a first draft. Neither should you. Prompting is iterative by nature.
→ FIX: Build revision prompts into your workflow: “Now improve the opening paragraph to be more direct” or “Make this 20% shorter without losing substance.” - Ignoring temperature settings entirely
Default temperature produces default-quality output. The model needs creative freedom for brainstorming and tight constraints for technical tasks.
→ FIX: Use 0.2 for factual/analytical tasks, 0.8–1.0 for ideation, 0.5 for balanced editorial work. - No shared prompt standards across teams
When every person on a team prompts differently, output quality varies wildly and institutional knowledge never accumulates.
→ FIX: Build a prompt library. Document what “good output looks like” for each task type. A/B test variations systematically.
Measuring & Improving Prompt Performance
Most people never measure their prompts. That’s like running paid ads without checking ROAS. Here’s a simple system.
The metrics that matter
| Metric | What to Measure | Target |
|---|---|---|
| Relevance Score | Does the output address the actual task? (rate 1–10) | 8+ consistently |
| Revision Rate | % of outputs requiring significant human editing | < 30% |
| Token Efficiency | Output quality per token spent | Improve 10% per month |
| Task Time | Total time including prompting + revision | Benchmark against baseline |
| Consistency Score | Run same prompt 5x — how similar are outputs? | High for factual, variable OK for creative |
A/B testing that actually works
Change one variable at a time. Tone. Structure. Level of role specificity. Length of context. Running these as controlled experiments — even informally — compounds fast. The team that documents “this prompt format consistently outperforms that one for our use case” is the team that builds a durable advantage.
OpenAI’s practical startup guide recommends pinning production prompts to specific model snapshot versions and building evals before making any changes. Even for smaller operations, a simple spreadsheet tracking “prompt version, task type, quality score” pays off within weeks.
Career & Salary Guide: The Honest 2025 Picture
Let’s cut through the hype and the doom in equal measure, because both are misleading right now.
What the compensation data actually shows
| Experience Level | Salary Range (US) | Total Comp (incl. equity) |
|---|---|---|
| Entry (0–1 yr) | $90K–$130K | $100K–$150K |
| Mid-level (2–4 yr) | $140K–$175K | $160K–$220K |
| Senior (5+ yr) | $200K–$270K | $270K–$400K+ |
| Median (Glassdoor Dec 2025) | $126K | — |
Glassdoor data as of December 2025 puts median total pay at $126K, with top-tier specialists at big tech companies earning $120K–$250K base. The outlier headline numbers ($335K–$375K) were real — OpenAI and Anthropic both posted those roles — but they represented a very specific moment of acute scarcity that has since partially normalized.
The real career trajectory
The job title “Prompt Engineer” is transitioning. What’s emerging is clearer: companies need people who combine prompting expertise with domain knowledge. A financial analyst who prompts brilliantly is worth more than a generic prompt engineer who knows nothing about finance. Vertical specialization is where the ceiling sits highest.
According to industry analysis, demand for these professionals still exceeds supply by roughly 5:1 in major tech hubs. The market expanded by 350% between 2023 and 2026, and the trajectory continues upward — just with different titles on the job posting.
If you’re building toward this field: pick a domain. Healthcare, legal, finance, engineering — it doesn’t matter which. Become the person who understands both the domain and the AI. That intersection is where the most durable, well-compensated work lives.
Ethics & Responsible Prompt Engineering
This section isn’t here to be preachy. It’s here because ethical failures in AI prompting have real business consequences — legal liability, reputational damage, and in high-stakes domains like healthcare, direct harm to people.
Bias mitigation in practice
Poorly designed prompts can systematically skew AI output in ways that are hard to detect. A healthcare AI that doesn’t account for gender differences in symptom presentation, or a hiring tool that over-indexes on language patterns associated with certain demographics, isn’t a future risk — it’s a documented present reality. The fix isn’t complicated: include inclusive language explicitly (“consider diverse demographics including gender, age, ethnicity, socioeconomic background”) and test outputs across varied scenarios.
The transparency obligation
AI-generated content that is passed off as human-authored, or AI analysis that’s presented without disclosing model limitations, erodes trust rapidly when it comes out — and it comes out. Disclosure practices are evolving from best practice to regulatory requirement in healthcare, finance, and journalism. Getting ahead of that is straightforward; getting caught behind it is not.
Privacy and data handling
Never include sensitive personal data, proprietary business information, or regulated data (HIPAA, GDPR-sensitive categories) in prompts to public API endpoints without explicit data processing agreements. This is not optional. Build prompts that work with anonymized examples and synthetic data wherever possible.
- Use inclusive language in prompts as a default, not an afterthought
- Implement fact-checking steps for any output that will influence decisions
- Require human review for high-stakes applications — medical, legal, financial
- Maintain version-controlled prompt libraries to audit what generated what output
- Flag AI-generated content clearly in any public-facing context
Frequently Asked Questions
The Bottom Line
Prompt engineering isn’t a trick or a shortcut. It’s the operational skill of working with AI effectively — and like every professional skill, it rewards people who take it seriously and punishes those who assume they can wing it.
The techniques in this guide aren’t theoretical. They’re derived from OpenAI’s own documentation for GPT-5.2, from Cursor’s real engineering work with GPT-5, and from the patterns that show up consistently in high-output, professional AI workflows.
Start with one template. Run it seriously for a week. Measure the output quality against your baseline. Iterate. That compound loop — prompt, measure, improve — is what separates casual AI users from the people who build genuine leverage with these tools.
Ready to go deeper?
Explore our full Prompt Engineering Course Guide and our detailed breakdown of ChatGPT-specific techniques — both updated for 2025’s latest models.
Explore Courses →Contact
Top 10 Prompt Engineering Strategies for 2026: Unlock AI Potential and Boost Productivity by 40%
Prompt Engineering Tips: Master AI with Latest Techniques
Master Prompt Engineering: 10 Essential Tips for Beginners in 2026
Prompt Engineering Best Practices: 2026 Guide
AI Remote Jobs: Complete Guide to Work-From-Home AI Careers
AI Freelance Salary: The Ultimate Guide to Earning Premium Rates in the Post-Gig Economy
Gallery